The STAR Method Makes You Sound Like Everyone Who Read the Same Blog Post
The STAR method doesn't make your answer good. It makes your answer complete, which is a different thing, and completeness is now the most common answer in the room. When every candidate spends the first thirty seconds setting the scene and the last five reporting the result, the format stops carrying signal. The interviewer has heard the arc forty times this month. They are not impressed that you know it. They expected it.
Here's what most people get wrong. They think a behavioral interview is graded on whether you hit all four letters. It isn't. It's graded on whether the interviewer believes the story happened and can remember it the next morning when they fill out the scorecard. The real driver is specificity and a clear point of conflict, not a tidy four-part structure. The template optimizes for the wrong variable, and almost everyone is optimizing for it at once.
What is the STAR method actually telling you to do?
It's telling you to spend your words in a fixed ratio that minimizes the only part that matters. That's the problem hiding in plain sight.
Look at the canonical guidance. MIT's career office, whose template a huge share of coached candidates have effectively absorbed, recommends you allocate your answer roughly 20% Situation, 10% Task, 60% Action, and 10% Result, with the explicit instruction that "most of your response should focus on your Actions." Read that ratio again. You're told to spend 60% of your airtime narrating what you did, and a tenth of it on what changed because you did it.
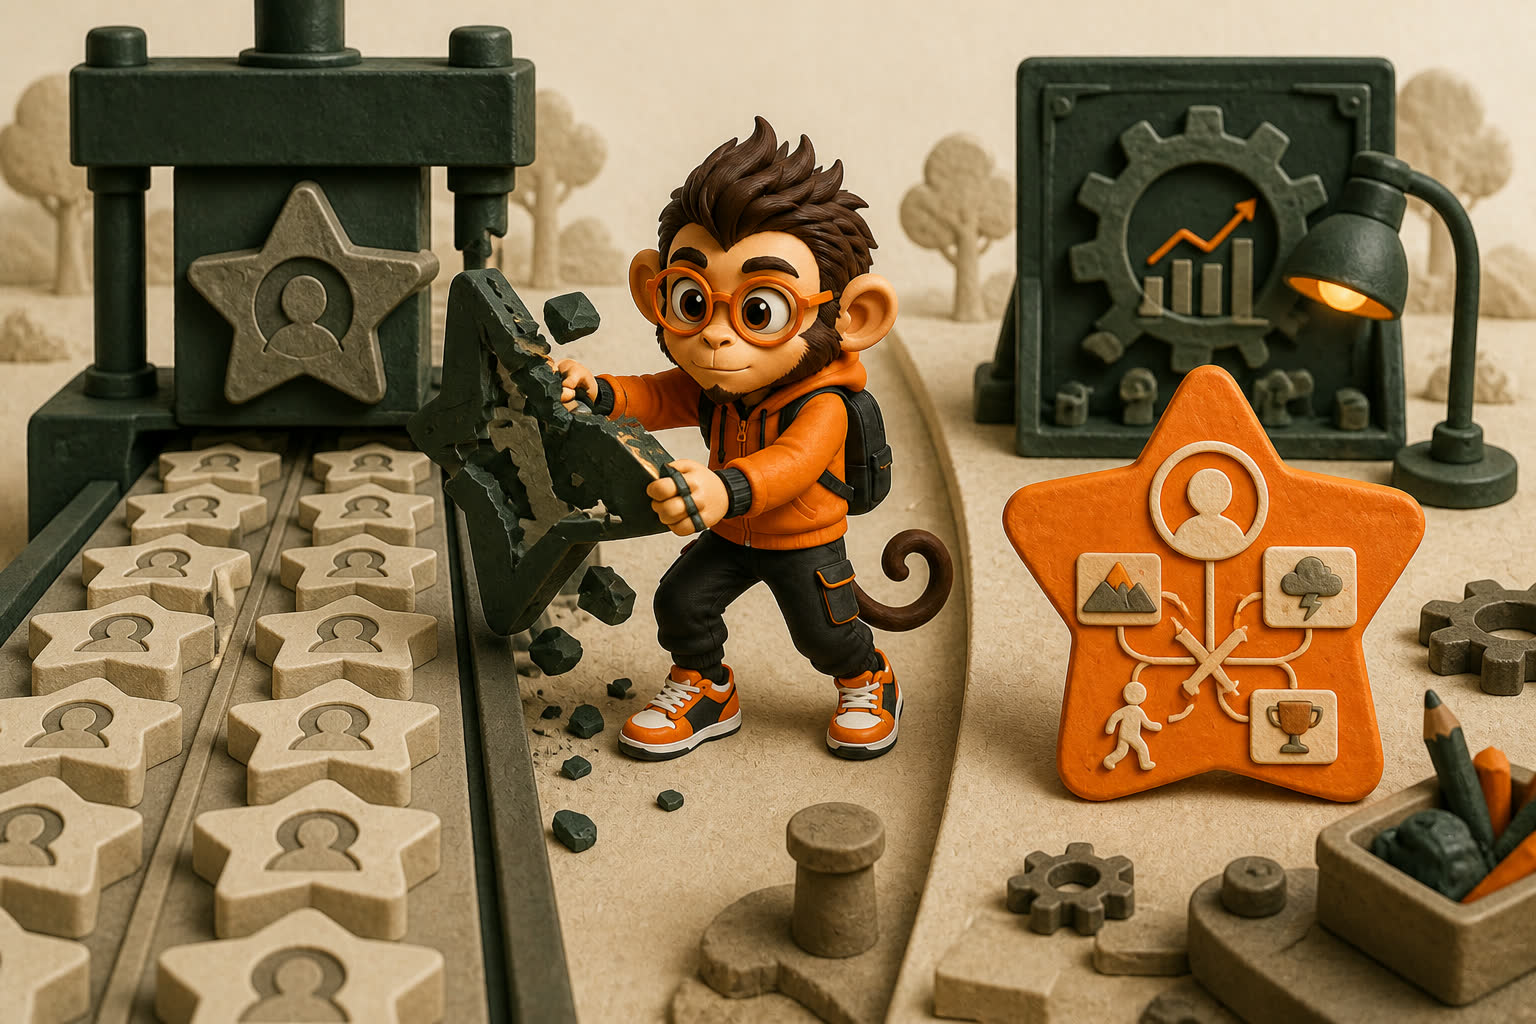
That ratio produces a very recognizable answer. Thirty seconds of context nobody asked for, a long middle of process narration, and a rushed outcome tacked on at the end. It's the shape every coached candidate fills in, because they were all handed the same skeleton. The format doesn't differentiate you. It synchronizes you with everyone else who read the same page.
Why do template-perfect answers blur together?
Because memory is built to compress the typical and keep the strange. A textbook answer is, by construction, typical.
There's hard cognitive evidence for this. In a schema-and-memory experiment, generic, schema-consistent items, the "of course that's how it goes" content, produced nearly double the false-memory rate of distinctive items, a 0.40 false-alarm rate for schematic lures versus 0.21 for non-schematic ones. The expected, well-formed answer is the one your interviewer is most likely to misremember and confuse with someone else's. Distinctive details are what stay attached to your name.
Think about what that means at the scorecard stage. The interviewer isn't replaying a recording. They're reconstructing you from a few fragments. If your fragments are all schema, "led a project, faced a challenge, took action, drove results," they collapse into the generic candidate template that every other STAR answer also fits. The detail that survives, the specific number, the awkward moment, the thing that went wrong before it went right, is the hook your name hangs on. A perfectly smooth answer gives the memory nothing to grab.
Doesn't a polished answer at least signal preparation?
It signals preparation that everyone else also has, which is the same as signaling nothing. The polished, managed answer isn't an edge anymore. It's the baseline.
The numbers on this are stark. In selection interviews, up to 99% of applicants use impression-management tactics, and over 90% report using at least some interview faking. Worse for the template believer, the research on interview impression management finds that applicants who use these managed tactics "tend to be evaluated more favorably" and that faking "inflate[s] interviewer evaluations of the candidate." So the polished answer is both ubiquitous and rewarded, which is exactly the condition under which it stops working as a signal. When nearly everyone runs the same managed playbook and it's rewarded, the playbook becomes background noise. You don't stand out by playing it better. You stand out by carrying something a managed answer can't manufacture.
And the thing it can't manufacture is verifiable specificity. A faked or over-coached story stays vague on purpose, because vague is safe. Real conflict, exact numbers, the name of the constraint you were under, these are hard to invent under follow-up and easy to recall when they're true. That's where the believability lives. Not in the structure. In the texture the structure was busy minimizing.
What actually predicts a good answer, then?
Relevance and substance, not polish. The empirical work here is recent and blunt about it.
A 2026 analysis built a corpus of 343 interview transcripts and 16,940 responses across 14 real projects and asked what separates a high-quality response from a forgettable one. The finding cuts straight at the template: "direct relevance to a key research question is the strongest predictor of response quality," while "clarity and surprisal-based informativeness are not predictive of response quality." Read that as a hiring sentence: substantive relevance to what the interviewer is actually probing beats how clean and well-structured your delivery sounds. The smooth, complete, four-part arc that STAR optimizes for is precisely the dimension the evidence says doesn't predict quality.
So the move isn't to abandon structure. It's to reallocate it. Lead with the result and the stakes, surface the conflict early, and spend your detail budget on the one or two specifics that prove the story is yours. Let the interviewer's follow-up questions pull the rest.
Weak (textbook STAR, ratio-perfect, forgettable): "So the situation was, our team was working on a customer onboarding project and we had a tight deadline. My task was to make sure we delivered on time. So what I did was, I organized the team, I set up daily standups, I communicated with stakeholders, I prioritized the backlog, and I made sure everyone was aligned. As a result, we delivered the project successfully and the client was happy."
Strong (result-first, conflict-forward, specific): "We shipped onboarding three days late, and I'm the reason it wasn't three weeks late. Two days before launch our payments vendor changed an API without notice and broke account creation for new users. I made the call to ship with a manual fallback for the first 200 accounts instead of slipping the date, took the support load myself for the first week, and we cut over to the fixed integration on day eight. We kept the launch, the churn hit was under 1%, and the postmortem I wrote became the vendor-change checklist the team still uses."
Same four letters are technically present in the strong version. But it opens on the outcome and the tension, names a specific failure, and hands the interviewer concrete hooks: 200 accounts, day eight, under 1%, a checklist that outlived the project. That's the answer they can still describe tomorrow.
So is the STAR method useless?
No, and anyone who tells you to throw out structure entirely is selling you the opposite mistake. Structure genuinely predicts hiring outcomes. The nuance is whose structure.
The validity evidence is strong. Schmidt and Hunter's foundational meta-analysis of 85 years of research put structured interview validity at r = .51, tied with general mental ability at the top of the selection hierarchy. The most recent re-estimation revised the numbers but kept structured interviews on top, at a mean operational validity of .42, ahead of general cognitive ability at .31 and well ahead of unstructured ones. Structure matters. A lot.
But read what "structured" refers to in that research. It's the interviewer's structured evaluation, consistent questions asked of every candidate, anchored scoring rubrics, on the employer's side of the table. It is not you reciting a memorized Situation-Task-Action-Result on yours. That distinction is the whole point, and it's why structured interviews beat the hiring manager's gut regardless of how you format your answer. The validity lives in how they grade, not in whether you hit all four letters. Format completeness is not the thing carrying the signal.
| What carries the signal | What people think carries it |
|---|---|
| The employer's structured evaluation, validity .42 | The candidate reciting four labeled parts |
| Direct relevance to the question being probed | Clarity and a smooth, complete arc |
| Distinctive details, 2x more memorable | Hitting Situation / Task / Action / Result in order |
| A specific point of conflict you owned | A long Action section (60% of airtime) |
Keep STAR as a checklist for completeness in your prep, so you don't forget the result. Drop it as the running order of your delivery.
The part nobody mentions: when the template is the right move
Here's where the contrarian take needs a guardrail. Sometimes the generic, complete answer is the correct one, and pretending otherwise gets people hurt.
If you're a nervous interviewer, early in your career, or non-native in the interview language, a clean STAR structure is a scaffold that keeps you from rambling or freezing. A forgettable-but-complete answer beats a memorable disaster every time. The advice to "drop the template" assumes you can hold a story together without it. Not everyone can yet, and that's fine. Build the muscle on the scaffold first, then start leading with the result once the structure is automatic. This is the same reason confidence is coachable while competence isn't fakeable: you earn the freedom to improvise by drilling the fundamentals until they hold under stress.
Two more honest caveats. First, in a heavily structured, rubric-scored process, the scorers may be checking for specific competencies in a specific order, and a tidy STAR answer maps cleanly onto their checklist. Read the room. Second, the conflict-forward move only works if the conflict is real and you genuinely owned your part. Manufacturing drama reads as exactly the impression-management the evidence already says everyone is doing. The edge is a true specific, not a performed one.
And one thing the template never covers at all: the interviewer has to like talking to you. Likeability beats raw competence in interviews more often than candidates want to believe, and no amount of perfect four-part structure substitutes for being a person the room wants to keep talking to. A result-first, conflict-forward story is also just a better conversation. It invites the follow-up. The textbook arc closes the loop and leaves the room quiet.
What to do now
- Take your three strongest stories and rewrite each to open on the result and the stakes. First sentence states the outcome and what was at risk. The context comes second, in one line, only if it's needed to understand the stakes.
- Find the conflict in each story and move it to the front. What broke, what was the constraint, where did it almost go wrong? If a story has no tension, it has no hook, pick a different story.
- Plant two or three verifiable specifics per answer. A number, a name, a date, a thing that outlived the project. These are the distinctive details that survive in memory while the generic arc blurs out.
- Keep the result. Cut the throat-clearing. Use STAR as a prep checklist so you never forget the outcome, then deliver in result-conflict-detail order, not S-T-A-R order.
- Apply the same logic to the questions that decide the most. The reframe matters most on the openers and the trap questions, like how you answer "why are you leaving", where a specific, non-defensive story beats a polished evasion every time.
Want to pressure-test your stories before the real interview? Message me on WhatsApp. We'll find the conflict in each one, cut the filler, plant the specifics that stick, and rehearse until your answers sound like you instead of like the blog post everyone else read.
Related reading
The Interviewer's Gut Feeling Is the Least Predictive Thing in the Room
Unstructured interview bias explains barely 4% of job performance. Here's how to give a gut-feel interviewer answers that survive the vibe filter.
Interviews Reward Confidence Over Competence. Here's How to Stop Losing to It.
Interviews reward confidence over competence because fluency is a proxy for skill. Here's how to make your real ability legible and stop losing rooms.
They Hire the Person They'd Want to Get a Beer With. That's the Bug to Exploit.
Likeability vs competence in hiring: warmth gets judged first and often outweighs raw skill. Here's how to signal both and stop playing on hard mode.
How to Answer 'Why Are You Leaving?' When It's Complicated (2026)
Leaving for a hard reason? Here's how to answer 'why are you leaving?' honestly without oversharing or lying, with real scripts for the messy cases.